Kim OlsenAI consultant in Copenhagen. I build internal AI tools on Claude for Nordic B2B sales teams.
Test whether the right Claude skill loads when your sellers ask.
Your team shares skills for call prep, recaps, proposals and pricing. A seller types a short, messy request, and Claude picks a skill from its name and description. Nobody sees which one. The runner asks Claude for every request on your list, scores the pick against your labels and shows you every miss.
What you get.
- The test runner: one Python file you point at your skills folder and a list of requests, each labelled with the skill that should load
- Twenty sales skills written as a team writes its first version, seven of them the original library and thirteen added as neighbours
- 56 requests, short and messy, Danish and English, labelled for both libraries, and a CSV template for your own
- My scored runs: which skill Claude loaded for every request, three runs each, before and after one rewrite
- Offline tests for the runner, and a README in English and Danish
What my test showed.
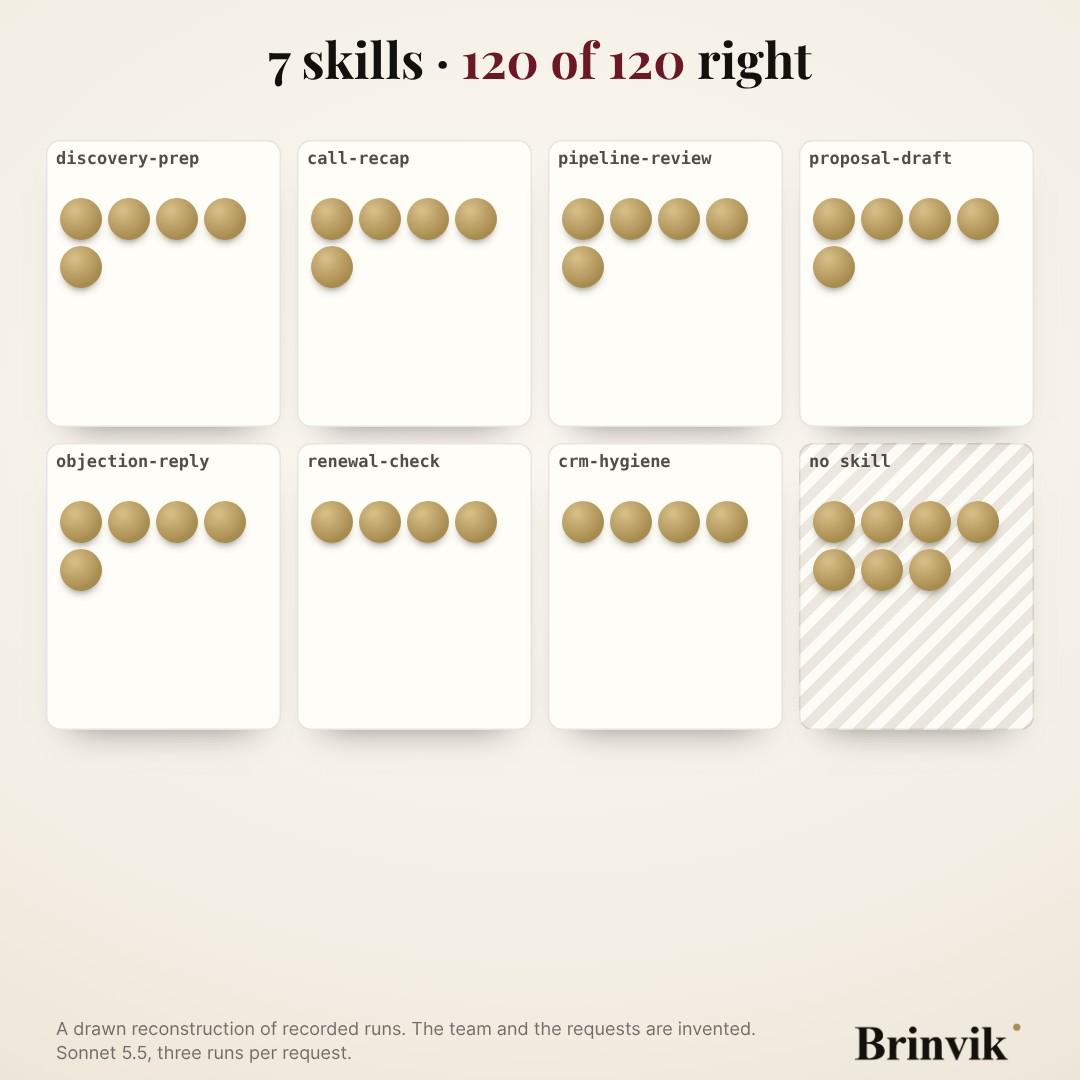
120 of 120
runs loaded the expected skill, or rightly none, with seven skills that do clearly different jobs.
117 of 120
with twenty skills that overlap. The one miss was a quick discount sum that loaded the pricing skill.
1 fixed, 2 broken
when Claude rewrote that one description: the sum was fixed, and two requests for a tilbud that were right before went to the pricing skill in every run.
A test on an invented team.
The team, the skills and the requests are invented, and the labels were set by the builder. One model, Sonnet 5.5, three runs per request. The runner is my reconstruction of how a skill is picked, not Claude Code’s or claude.ai’s own loader, so a result says whether a description steers Claude well. It uses your own API key and never stores it.
Read what this means for a sales team that shares skills: Claude fixed one skill description. Then it took its neighbour’s requests →